Automation reliability
Make a daily AI automation useful on the days things go wrong
Design a daily AI workflow with fresh inputs, visible review, duplicate protection, failure recovery, and a clear owner.
In this guide
- The useful starting point
- Define what a successful run means
- Use a small state model
- A fictional example: the morning operations brief
- Build and test the ordinary failure paths
- Use a reliability prompt before implementation
- Monitor usefulness as well as uptime
- Leave a useful handoff
- Hire for the failure cases as well as the happy path
- Questions you might be asking
- Sources and further reading
The useful starting point
A reliable daily AI workflow validates its inputs, produces a checkable result, records what happened, and stops safely when required data or permissions are missing. Test failure and recovery as carefully as the successful demonstration.
A daily automation is easy to like when the demonstration works. The real test arrives when a source is late, a field changes, an account disconnects, or the same trigger fires twice. Those ordinary problems should be part of the design.
Start with a modest outcome: a useful morning brief, a draft status report, or a queue of records to review. Give the workflow one job, one owner, and a visible way to stop it.
Define what a successful run means
Write a statement someone could verify. “Prepare a draft of today's unresolved customer handoffs from approved records, with source links and owners” is testable. “Keep the business running with AI” is not.
Then describe the minimum acceptable inputs. Which source must be available? How recent must it be? Which fields are required? What should happen if a record has no owner? A model should not quietly fill operational gaps with plausible guesses.
Define the destination too. A draft stored in a review queue, a task created in a project system, and a message sent to a customer are different outcomes with different consequences.
Use a small state model
| State | Meaning | Next step |
|---|---|---|
| Waiting for input | Required data is unavailable or incomplete | Wait, notify, or request repair |
| Ready for review | A draft passed basic checks | A person inspects the actual result |
| Approved | The defined action is authorized | Execute the permitted step |
| Completed | The destination confirms success | Record the outcome |
| Failed or uncertain | The result is not confirmed | Investigate before retrying |
Keeping these states separate prevents a common mistake: assuming that an approved action must have completed successfully. It also makes recovery easier for someone who was not present when the workflow ran.
A fictional example: the morning operations brief
Imagine a small studio that wants a daily list of overdue project decisions. The workflow reads approved project records, checks dates and owners, and prepares a short brief. AI helps turn the records into readable language, while ordinary rules identify overdue items.
One morning, the project system has not refreshed. Instead of reporting “No overdue decisions,” the workflow marks the data stale and creates an internal notice. Another day, a record lacks an owner. The brief lists it under “Needs assignment” rather than inventing responsibility.
A duplicate trigger does not create a second brief because the run has a stable identifier for the studio, date, and report type. The reviewer can see which records were included and correct a misleading summary before distribution.
This is a proposed example, not a deployed customer workflow. Its value comes from explicit behavior under imperfect conditions, not from promising that automation never fails.
Build and test the ordinary failure paths
- Validate inputs. Check required fields, formats, source freshness, and allowed scope before asking AI to interpret them.
- Constrain the output. Require a small structure with evidence links and unknowns, rather than an unrestricted essay.
- Check the result. Verify required sections, prohibited assumptions, and important calculations.
- Route review. Show the reviewer the draft, source context, and proposed action.
- Prevent duplicates. Look up the run or record identifier before creating another destination item.
- Log the outcome. Save enough information to understand what happened without storing unnecessary sensitive content.
- Practice recovery. Pause, repair, and replay the smallest safe step.
Automation platforms provide useful building blocks, but the logic remains your responsibility. n8n documents approval for selected agent tools. Zapier documents human review steps in Zaps. Make can combine modules and scenarios. Choose the structure that your team can understand and maintain.
Use a reliability prompt before implementation
Review this proposed daily workflow. Identify how it behaves with stale data, a missing field, an expired connection, duplicate triggers, a rejected draft, and an uncertain destination result. For each case, specify whether it should stop, retry, or request human help. Define the owner, stable identifier, review evidence, and recovery step. Prefer simple rules where they are sufficient. Do not assume a tool action has succeeded without confirmation.
Ask another person to walk through the answer using one failed case. If they cannot understand how to recover, the design needs clearer states or simpler steps.
Monitor usefulness as well as uptime
A workflow can run every day and still waste attention. Track whether reviewers use the result, how much correction it needs, and how often it flags something that matters. Record preparation and review effort alongside execution time.
Keep a small set of representative test cases. Rerun them when instructions, models, sources, or tool permissions change. Include an easy case, an incomplete case, a conflicting case, and a case that should stop.
Do not treat a successful run as permission to expand access automatically. Add one source or action at a time and verify the new boundary.
Leave a useful handoff
Document the purpose, source accounts, owner, schedule, pause control, and last known working configuration. Explain how to reconnect an account through the official interface and where to find failures. Keep credentials in the platform's supported credential system, not in the instructions.
If the automation becomes more complicated than the work it saves, simplify it. A reliable draft with a clear reviewer can be more valuable than a chain of clever actions that nobody feels comfortable changing.
The daily habit you want is steady assistance with visible limits. Build for the imperfect morning, and the successful mornings become easier to trust.
Hire for the failure cases as well as the happy path
A freelance automation specialist can help implement a bounded workflow when you have a clear process but lack the integration skills. Put duplicate prevention, permission boundaries, alerts, rollback, and operating instructions in the brief. Ask the specialist to demonstrate a failed run and its recovery before handoff.
Affiliate disclosure: We may earn a commission if you become a qualifying Upwork customer through this link.
Explore hiring on Upwork. Compare relevant work, agree on a small paid milestone, and review the deliverable before expanding the project. Marketplace access does not guarantee a suitable hire or business results.
Questions you might be asking
Should a daily automation retry every failure?
No. Retrying can duplicate an action or repeat a bad input. Classify failures and inspect uncertain destination results before retrying consequential steps.
What should I monitor?
Track successful completion, stale inputs, errors, duplicate prevention, review effort, corrections, and whether the output led to useful action.
When should I pause the workflow?
Pause when required data is unreliable, scope is wrong, important actions are uncertain, or errors exceed the team's acceptable boundary. Repair and test before resuming.
Sources and further reading
Sources checked October 16, 2026. Review the linked publisher information for current details.
Put one idea to work
Separate rules, AI assistance, review, and recovery before turning a useful task into an unattended process.
Map your first workflow →Explore more from AutomatelyKeep practicing
 Agent orchestration
Where an AI agent belongs inside a reliable workflow
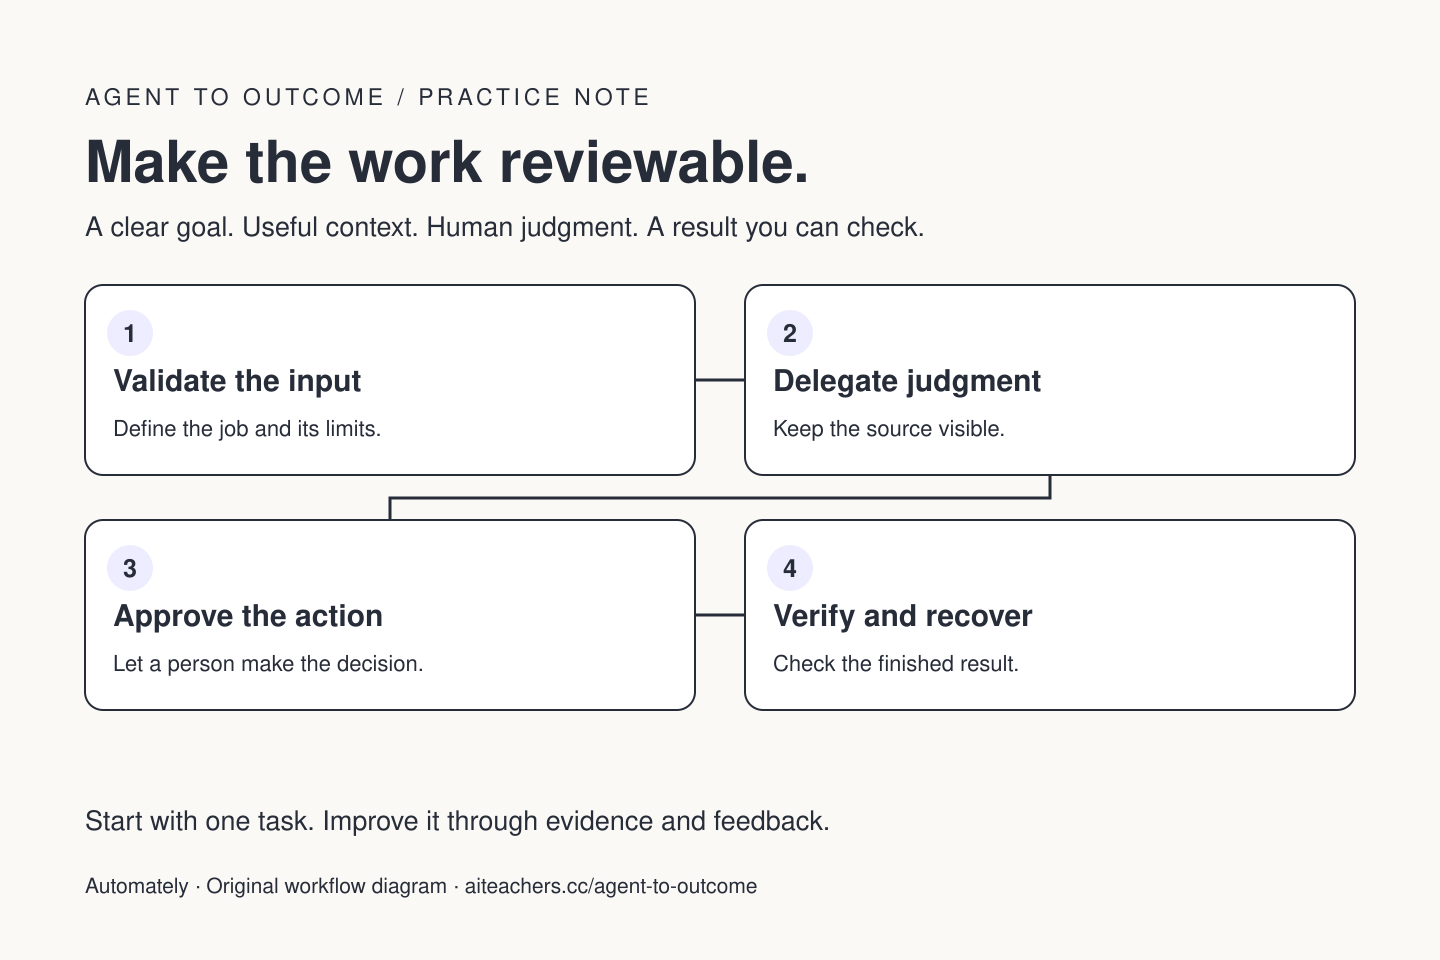
Separate fixed rules, agent judgment, specialist handoffs, human approval, and recovery before automating a recurring business task.
October 23, 2026 · 4 min read Freelance work
Upwork MCP for automation specialists: sell a workflow you can support
A practical Upwork MCP workflow for automation builders and operations specialists: project fit, honest proposals, bid review, portfolio evidence, and a small side-work test.
October 20, 2026 · 4 min read